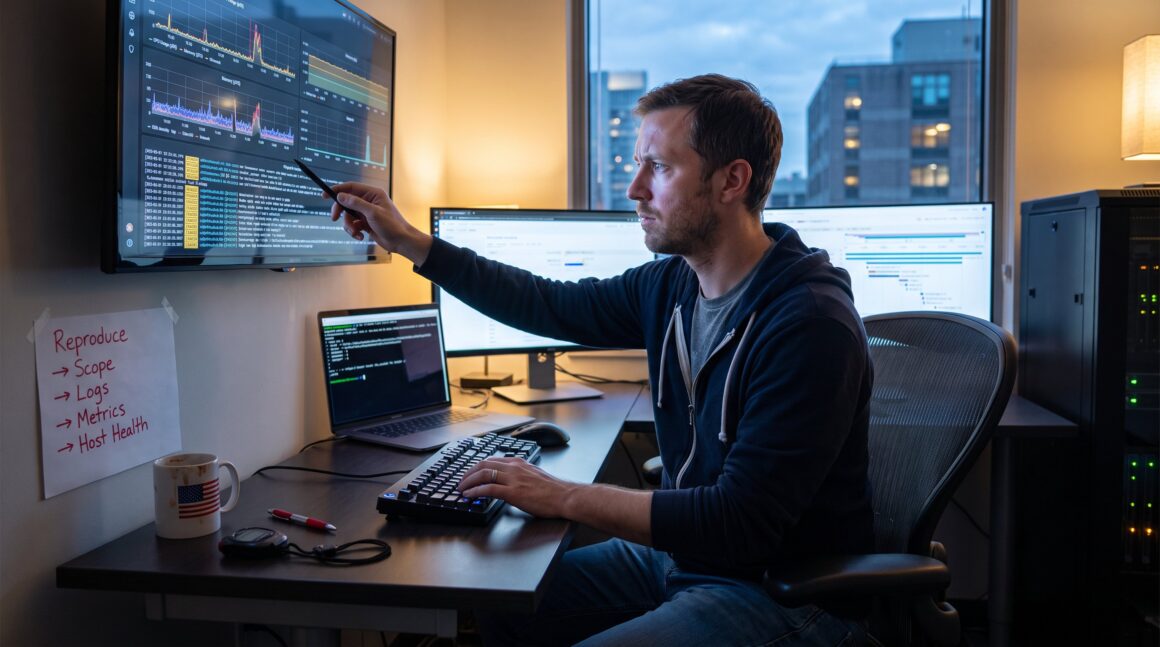
How to Troubleshoot Common Software Performance Problems starts with a reproducible test case and clear scope. The team should first confirm whether the slowdown is one user’s issue, a cluster-wide regression, or an infrastructure failure. This checklist focuses on fast diagnosis: reproduce the problem, scan recent changes, inspect logs and metrics, and check basic host health. The goal is to move from symptom to root cause within an hour, or gather evidence that justifies escalation.
Key Takeaways
- Reproduce the software performance issue with a minimal test case to accurately define its scope before troubleshooting.
- Use the quick diagnostic checklist: check recent changes, inspect logs and metrics, and verify basic host health to identify root causes fast.
- Identify the primary resource bottleneck—CPU, memory, disk I/O, or network—using appropriate tools to focus your troubleshooting efforts.
- Apply targeted fixes matching the bottleneck: optimize code or queries for CPU, fix memory leaks, improve disk handling, and tune network configurations.
- Prioritize patching only when updates explicitly address performance bugs and test upgrades in staging before production rollout.
- Escalate issues when repeated targeted fixes fail to improve performance, particularly if external services or infrastructure limits are involved.
Quick Diagnostic Checklist — What To Check First
Start with the fact: reproduce the issue and define its scope before changing anything. If the team cannot reproduce the slowdown, they cannot measure improvement.
Reproduce and scope
- Reproduce with a minimal test case: same request, same dataset, same user role. Note whether the problem is single-user, multi-user, or system-wide.
Recent changes
- Check deployments in the last 24–72 hours: app binaries, database schema migrations, configuration flags, and OS or driver updates. A single config flip often explains sudden regressions.
Logs and metrics
- Inspect application logs for error spikes, stack traces, and timeout messages. Correlate with APM traces and query logs to find slow endpoints.
Basic health checks
- Confirm uptime, load average, memory usage, free disk space, and hardware temperatures. A host with a 95% partition or sustained high temp points to immediate action.
Practical tip: capture a short, repeatable recording of the failing request (HTTP headers, payload size, and timestamps). That single recording often shortens debugging by 30–60 minutes.
Diagnose Resource Bottlenecks: CPU, Memory, Disk, And Network
Answer first: identify which resource shows the tightest constraint, CPU, memory, disk I/O, or network, and focus there.
CPU
Tools: top, mpstat, vmstat, Windows Task Manager. Look for sustained user/ system utilization above 80% and long run queues. If one process consumes 60–90% CPU during a slow window, profile it immediately. Profiling will reveal hot functions or GC pauses.
Memory
Tools: free, vmstat, Task Manager. Watch for paging, swap activity, and hard faults/sec. Hard faults rising above baseline by orders of magnitude mean the process is thrashing. Example: an API server that starts swapping will show latency jumps from 50ms to 2,000ms.
Disk I/O
Tools: iostat, iotop, Resource Monitor. Key signals are %util near 100%, high await, and long queue lengths. Low free space (<10%) also degrades performance. If logs and writes share the same device as the database, separate them.
Network
Tools: ifstat, sar, netstat. Inspect retransmissions, errors, and connection counts. High retransmits or rising RTTs indicate packet loss or congestion. For API dependencies, measure 95th percentile latency to external services.
Practical example: a web cluster showed 85% CPU but low disk I/O: after profiling, a JSON serializer was the hot path. Replacing it reduced CPU by 40% and request p95 by 300ms.
Targeted Fixes For The Most Common Performance Issues
Immediate answer: match the fix to the bottleneck, optimize code or queries for CPU issues, fix leaks for memory, move or cache for disk I/O, and optimize transport for network problems.
Fixes for CPU-bound systems
- Profile to find hot paths. Replace inefficient loops, optimize database queries, and eliminate excessive serialization. If profiling shows a single query dominates CPU, add an index or rewrite the query. When demand exceeds a single node, scale horizontally behind a load balancer.
Memory pressure solutions
- Fix memory leaks, reduce cache sizes, and tune runtimes (for example, JVM heap settings). For a web app that used 1.2 GB per process, lowering cache TTLs from 24 hours to 6 hours cut memory by 35% and reduced swapping.
Disk I/O remediation
- Optimize queries and indexes to reduce full-table scans. Enable caching layers (Redis, Memcached), move heavy writes to faster storage (SSD or NVMe), and separate log volumes. In one case, moving write-heavy analytics to an NVMe node reduced query latency p99 from 4s to 120ms.
Network tuning
- Use CDNs for static assets, enable HTTP keep-alive and connection reuse, reduce payload size with compression, and fix MTU problems or routing blackholes. For dependent APIs, carry out circuit breakers and timeouts so a slow downstream service cannot cascade.
When to patch or upgrade
- Apply vendor patches when they explicitly address documented performance bugs. If an upgrade includes GC improvements or driver fixes, test in a staging environment with production-like load before rolling out.
Contextual resources: teams maintaining broader system practices may benefit from the site overview on operational patterns provided by site overview. Also, engineers comparing hardware choices should review a concise piece about comparing gadget specs for practical decision factors.
Warning: quick fixes that mask the root cause (for example, blindly increasing instance size) can hide architectural debt. Prefer measured changes with before/after metrics.
Conclusion — When To Patch, Optimize, Or Escalate
Direct takeaway: patch when a vendor hotfix or security update specifically fixes a documented performance defect: optimize when profiling shows clear, solvable bottlenecks: escalate when the issue involves external services, unclear root causes, or infrastructure limits.
A sensible escalation path: reproduce -> isolate resource -> apply targeted fix in staging -> measure improvement -> roll out gradually. If the team cannot reduce p95 latency after two targeted iterations, escalate to networking, hosting support, or the vendor.
Final note: building a short runbook that lists the checks above reduces mean time to resolution. For developers learning the necessary skills, the learning roadmap offers practical next steps.